Typed Crystallization Networks
Learn a typed program the way a network learns, then commit it to an immutable, exact, content-addressed program that later tasks reuse as a new operator. Exact where networks are approximate, and honest about where it loses.
- A network whose structure is a typed program. Every node chooses among the legal (operator, binding) pairs for its types; illegal wiring never enters the softmax, so legality is built into the structure rather than learned from a penalty
- Crystallization turns that soft structure into an immutable program: take the argmax, prune, content-address. The result is exact, gradient-free, and reproduces its fixture bit for bit
- Published programs become new operators, so a later task can build on an earlier one; abstraction is recursive, not a one-off
Problem
A trained network is an approximation of the function you wanted, and you cannot take one piece of it and reuse it somewhere else with any guarantee. If a model learns to parse a bracket, the parse lives smeared across weights that also do everything else, and the next task starts from zero. Program synthesis gives you exact, reusable pieces, but it usually works only when someone hands the searcher a domain-specific language with the right primitives already in it.
I wanted both halves. Learn structure from experience the way a network does, with no domain receiving a primitive that every other domain can't also use, and then commit what was learned to something exact that later tasks can call.
Solution
TCN learns inside generated transition systems: worlds with an observation, an objective and a set of legal actions. The learner is a soft typed program graph, trained on prediction, probes and reward at the same time. Values are typed (bool, int[n], sets, tuples) and carry roles, so a value used as a magnitude can't silently be used as a name.
When a stage is learned, it is crystallized: the soft graph becomes an exact program, written out as content-addressed, stdlib-only Python, and published to a library. The library feeds the operator registry, so the next stage's graph can choose the published program as one of its candidates.
1/8 The world host shows the actor only what it is allowed to see: observation, objective, legal actions.
The name is not a freezing schedule. I tried progressive, irreversible freezing four separate ways, and plain argmax at equal compute beat all of them (3.78 and 3.63 against 2.94 and 2.53). The project kept the word for the conversion and dropped the schedule.
How
- Language / runtime: Python and NumPy, no deep-learning framework; exported programs run on the standard library alone
- Learning: REINFORCE with a value baseline and entropy bonus, prediction and probe losses on recorded latents, and regularizers for description length and discreteness
- Discrete backend: for many tasks it is faster to search for the program than to descend to it, so a router picks between enumeration, recurrent search, environment search and prefix search, and returns a certificate when the space was exhausted
- Scale: 343 commits over four days, 14 generators, and a findings log of 66 sections, each tied to the raw JSON it was computed from
Results
The project's STATUS.md keeps two lists, what works and what was measured not to work, and the second is as long as the first.
What works:
- Exact synthesis. Held-out maximum error ≤ 1e-7 on 584 points it never fitted, where a matched MLP manages 1.8e-2.
- Depth generalization. Trained only at depths 1–2, one fixed graph scores 4.00 at every depth from 1 to 8, with zero variance over eight seeds, where the best constant manages 2.06–2.50. It is the certified-unique optimum of its 272-program space.
- Recursive abstraction. In every one of 27 successes the published module is on the output path. The equivalent flat search space, 230,400 programs, was exhausted without finding a solution.
- A language task from raw bytes. It discovers which byte opens a bracket and where the symbol field starts, unique among 10,496 candidate programs, then reaches 1.000 on 859 held-out episodes at lengths it never trained on. The majority constant scores 0.526, and gradient descent finds a conforming program in 0 of 64 runs.
- Dense supervision is what makes it tractable. Supervising intermediate regions takes free-wiring synthesis from 19–38% to 88–94%.
The honest trade-off. Against matched neural baselines the answer is different per task, and on GUI parsing it is both of these at once:
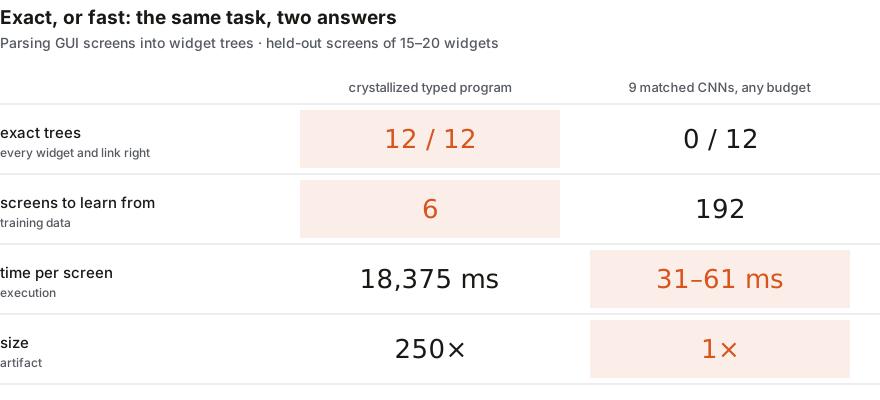 A crystallized typed program against nine matched CNNs on GUI parsing: 12/12 exact trees against 0, from 6 screens against 192, but 18,375 ms per screen against 31–61 ms and 250 times larger
What was measured not to work: gradient descent is not worth it as the search (brute force finds the program in 0.08 ms against 10–36 s, and the gradient path breaks first at depth 4); the description is far larger than what it learns (68,768 bits shipped for 8 bits of learned content); uncompiled programs are 146× to 90,400× slower; nothing learned in one domain was reused in another; and the integrated flagship missed its preregistered criterion, with the library costing 10,925× more than the alternative. A self-audit of the repository's own claims found 85 discrepancies among 794 cited figures, and corrected them in place, including one headline result that had been reported as 1.000 and was 723 of 724.
Lessons
Exactness is real and it is expensive. The typed program gets every tree right from a handful of examples where networks get none right, and it runs hundreds of times slower doing it; both facts are the result, and a page that showed only one would be selling something. The other lesson is about the method: the most useful file in the repository is the list of things that failed, and the audit that corrected the successes. Four days was enough to find that the parts I expected to matter (gradient search, the freezing schedule) didn't, and the part I added late (dense supervision of intermediate regions) was the one doing the work.